

Latin Hypercube Designs#
Latin hypercube sampling (LHS) divides each input’s marginal distribution into equal-probability intervals and places exactly one sample in each interval. For a continuous uniform input, these intervals have equal width. The coordinates are then paired to form the joint design.
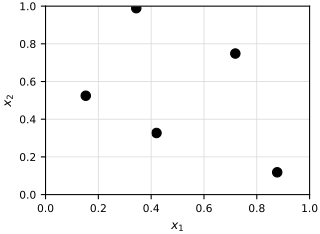
In two dimensions, this gives one point in each row and each column of the grid below. Every individual input is evenly covered, although the joint design need not fill the full input space evenly. The construction extends to any number of inputs.
import scipy.stats.qmc as qmc
import numpy as np
rng = np.random.default_rng(20260922)

# Define the number of dimensions and samples
dim = 2
num_samples = 5

# Create a Latin Hypercube sampler with the given dimensions
sampler = qmc.LatinHypercube(dim, seed=rng)

# Generate the samples (between 0 and 1)
X = sampler.random(n=num_samples)

# Plotting
fig, ax = plt.subplots(figsize=FIGURE_SIZES["half_standard"])
# Create the grid positions based on the Latin Hypercube intervals
grid_positions = np.linspace(0, 1, num_samples + 1)
# Set the grid to match the Latin Hypercube intervals
ax.set_xticks(grid_positions)
ax.set_yticks(grid_positions)
ax.grid(True)# Scatter plot for the Latin Hypercube samples
ax.scatter(X[:, 0], X[:, 1], 50., color="black")
ax.set_xlabel('$x_1$')
ax.set_ylabel('$x_2$')
finalize_axes(ax, keep_box=True)
ax.set(xlim=(0, 1), ylim=(0, 1))
ax.grid(True, color="0.85", linewidth=0.6)
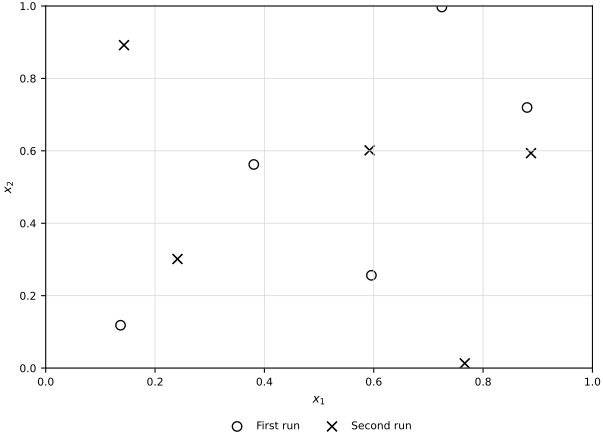
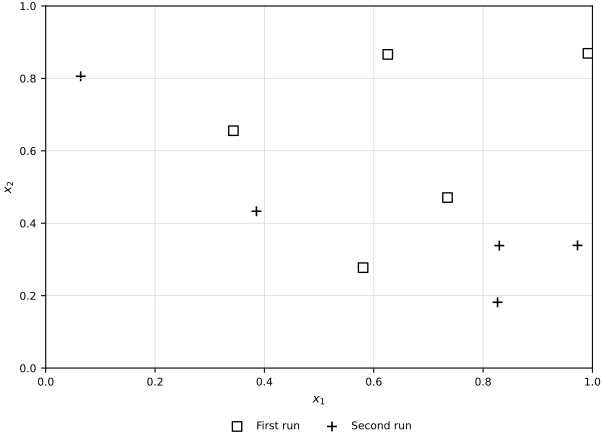
We can compare this to uniform samples in 2D.
# Number of samples
num_samples = 5

# Latin hypercube sampling
fig, ax = plt.subplots(figsize=FIGURE_SIZES["full_standard"])
sampler = qmc.LatinHypercube(d=2, seed=rng)

# First set of LHS samples
X_lhs = sampler.random(n=num_samples)
ax.scatter(
    X_lhs[:, 0], X_lhs[:, 1], 50.0,
    marker="o", facecolors="white", edgecolors="black",
    linewidths=1.0, label="First run",
)

# Second set of LHS samples
sampler = qmc.LatinHypercube(d=2, seed=rng)
X_lhs = sampler.random(n=num_samples)
grid_positions = np.linspace(0, 1, num_samples + 1)
ax.set_xticks(grid_positions)
ax.set_yticks(grid_positions)
ax.grid(True, color="0.85", linewidth=0.6)
ax.scatter(
    X_lhs[:, 0], X_lhs[:, 1], 55.0,
    marker="x", color="black", linewidths=1.2, label="Second run",
)

ax.set_xlim(0, 1)
ax.set_ylim(0, 1)
ax.set_xlabel("$x_1$")
ax.set_ylabel("$x_2$")
ax.legend(loc="upper center", bbox_to_anchor=(0.5, -0.12), ncol=2)
finalize_axes(ax, keep_box=True)
ax.grid(True, color="0.85", linewidth=0.6)

# Uniform sampling for comparison
fig2, ax2 = plt.subplots(figsize=FIGURE_SIZES["full_standard"])
X_unif = rng.random((num_samples, 2))
ax2.scatter(
    X_unif[:, 0], X_unif[:, 1], 50.0,
    marker="s", facecolors="white", edgecolors="black",
    linewidths=1.0, label="First run",
)

X_unif = rng.random((num_samples, 2))
ax2.scatter(
    X_unif[:, 0], X_unif[:, 1], 55.0,
    marker="+", color="black", linewidths=1.2, label="Second run",
)
ax2.set_xlim(0, 1)
ax2.set_ylim(0, 1)
ax2.set_xlabel("$x_1$")
ax2.set_ylabel("$x_2$")
ax2.set_xticks(grid_positions)
ax2.set_yticks(grid_positions)
ax2.grid(True, color="0.85", linewidth=0.6)
ax2.legend(loc="upper center", bbox_to_anchor=(0.5, -0.12), ncol=2)
finalize_axes(ax2, keep_box=True)
ax2.grid(True, color="0.85", linewidth=0.6)
Uniform Sampling vs Latin Hyper-cubes#
Consider the ODE:
The solution is \(y(t) = y_0 e^{-at}\). Let’s make \(a\) and \(y_0\) random and use Monte Carlo (MC) sampling and LHS to find the mean, \(E[y(t)]\), and the variance \(V[y(t)]\). We’ll take:
and
For convenience, let’s map these random variables to standardized uniform random variables:
This can be done by defining:
Using the new random variables, the ODE can be written as:
The “Solver” object#
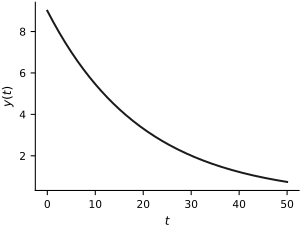
Let’s develop a solver for this problem. We’ll make the solver work as a nice function that accepts a vector \(\mathbf{x} = (x_1, x_2)\) as an input, and returns the solution of the ODE on a finite set of time-steps:
\(0=t_1<t_2<\dots<t_{n_t}=T\).
The solver, will make use of the functionality of scipy.integrate.odeint.
import scipy.integrate

# Define the ODE solver class
class Ex1Solver(object):
    """
    An object that can solver the aforementioned ODE problem.
    It will work just like a multivariate function.
    """

    def __init__(self, nt=100, T=5):
        """
        This is the initializer of the class.

        Arguments:
            nt - The number of time-steps.
            T  - The final time.
        """
        self.nt = nt
        self.T = T
        self.t = np.linspace(0, T, nt) # The time-steps on which we will get the solution
        # The following are not essential, but they are convenient
        self.num_input = 2             # The number of inputs the class accepts
        self.num_output = nt           # The number of outputs the class returns

    def __call__(self, x):
        """
        This special class method emulates a function call.

        Arguments:
            x - A 1D numpy array with 2 elements. This represents the stochastic input x = (x1, x2).
        """
        def rhs(y, t, x1):
            """
            This is the right hand side of the ODE.
            """
            return -.1 * x1 * y
        # The initial condition
        y0 = [8 + 2 * x[1]]
        # We are ready to solve the ODE
        y = scipy.integrate.odeint(rhs, y0, self.t, args=(x[0],)).flatten()
        # The only strange thing here is the use of ``args`` to pass they x1 argument to the rhs().
        return y
# Instantiate the solver
solver = Ex1Solver(nt=200, T=50)

# Now let's evaluate the solver at a specific input.
x = [0.5, 0.5]
y = solver(x)
print(y)
[9.         8.88764176 8.77668666 8.66711647 8.55891419 8.45206273
 8.34654522 8.24234502 8.13944568 8.03783094 7.9374848  7.8383914
 7.74053511 7.64390048 7.54847226 7.45423538 7.36117497 7.26927633
 7.17852497 7.08890658 7.00040701 6.91301231 6.82670868 6.7414825
 6.6573203  6.57420881 6.49213489 6.41108558 6.3310481  6.25200982
 6.17395828 6.09688115 6.02076628 5.94560164 5.87137538 5.79807577
 5.72569126 5.65421041 5.58362194 5.51391471 5.44507772 5.37710012
 5.30997115 5.24368025 5.17821693 5.11357087 5.04973187 4.98668985
 4.92443486 4.86295708 4.8022468  4.74229444 4.68309054 4.62462576
 4.56689086 4.50987674 4.4535744  4.39797495 4.34306962 4.28884974
 4.23530676 4.18243223 4.13021781 4.07865524 4.02773638 3.97745321
 3.92779777 3.87876223 3.83033886 3.78252001 3.73529813 3.68866578
 3.6426156  3.59714032 3.55223278 3.50788589 3.46409264 3.42084611
 3.37813949 3.33596603 3.29431907 3.25319203 3.21257843 3.17247185
 3.13286597 3.09375454 3.05513139 3.01699042 2.97932561 2.94213102
 2.90540078 2.86912908 2.83331021 2.79793852 2.7630084  2.72851437
 2.69445096 2.66081281 2.62759461 2.59479111 2.56239714 2.53040758
 2.49881739 2.46762157 2.43681521 2.40639345 2.37635147 2.34668455
 2.317388   2.28845719 2.25988756 2.2316746  2.20381386 2.17630094
 2.1491315  2.12230124 2.09580594 2.06964141 2.04380353 2.01828822
 1.99309144 1.96820922 1.94363764 1.91937282 1.89541092 1.87174817
 1.84838083 1.82530521 1.80251768 1.78001463 1.75779251 1.73584782
 1.7141771  1.69277691 1.67164389 1.6507747  1.63016604 1.60981467
 1.58971737 1.56987096 1.55027233 1.53091837 1.51180603 1.4929323
 1.47429418 1.45588875 1.4377131  1.41976435 1.40203968 1.38453629
 1.36725142 1.35018233 1.33332635 1.31668079 1.30024304 1.28401051
 1.26798062 1.25215086 1.23651871 1.22108172 1.20583745 1.1907835
 1.17591748 1.16123706 1.1467399  1.13242374 1.1182863  1.10432535
 1.09053869 1.07692415 1.06347958 1.05020286 1.03709188 1.02414458
 1.01135892 0.99873289 0.98626447 0.97395172 0.96179268 0.94978543
 0.93792809 0.92621878 0.91465565 0.90323687 0.89196065 0.88082521
 0.86982879 0.85896964 0.84824606 0.83765636 0.82719887 0.81687192
 0.8066739  0.7966032  0.78665822 0.77683739 0.76713918 0.75756203
 0.74810445 0.73876494]
# Let's plot it:
fig, ax = plt.subplots(figsize=FIGURE_SIZES["half_standard"])
ax.plot(solver.t, y)
ax.set_xlabel('$t$')
ax.set_ylabel('$y(t)$')
finalize_axes(keep_box=False)
array([<Axes: xlabel='$t$', ylabel='$y(t)$'>], dtype=object)
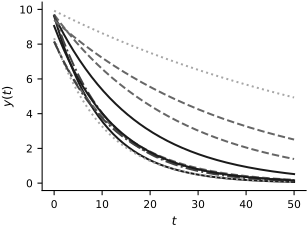
# Now, let's just plot a few random samples.
fig, ax = plt.subplots(figsize=FIGURE_SIZES["half_standard"])
for i in range(10):
    x = rng.random(2)
    y = solver(x)
    plt.plot(solver.t, y)
ax.set_xlabel('$t$')
ax.set_ylabel('$y(t)$')
finalize_axes(keep_box=False)
array([<Axes: xlabel='$t$', ylabel='$y(t)$'>], dtype=object)
Propagating Uncertainties with LHS#
Let’s propagate the uncertainties through the ODE using LHS.
# Initialize outputs
y_lhs = np.zeros(solver.num_output)  # Sum of outputs
y2_lhs = np.zeros(solver.num_output)  # Sum of squares of outputs

# Number of samples
num_samples = 10000

# Create the LHS design using scipy.stats.qmc
sampler = qmc.LatinHypercube(d=2, seed=rng)  # Assuming 2 dimensions, adjust `d` as needed
X = sampler.random(n=num_samples)  # Generate the LHS samples

# To store the results
data_lhs = []

# Loop through the samples
for i in range(num_samples):
    if i % 1000 == 0:
        print('sample', i + 1, 'from', num_samples)
    x = X[i, :]
    y = solver(x)  # Assuming solver returns a numpy array of outputs
    y_lhs += y  # Sum of outputs
    y2_lhs += y ** 2  # Sum of squares of outputs
    data_lhs.append(y)  # Store the output

# Convert the accumulated results into a numpy array
data_lhs = np.array(data_lhs)

# Compute the mean estimate
y_m_lhs = y_lhs / num_samples

# Compute the variance estimate
y_v_lhs = y2_lhs / num_samples - y_m_lhs ** 2
sample 1 from 10000
sample 1001 from 10000
sample 2001 from 10000
sample 3001 from 10000
sample 4001 from 10000
sample 5001 from 10000
sample 6001 from 10000
sample 7001 from 10000
sample 8001 from 10000
sample 9001 from 10000
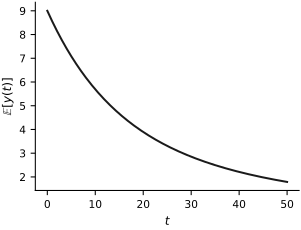
# Let's plot the mean
plt.plot(solver.t, y_m_lhs)
plt.xlabel('$t$')
plt.ylabel('$\mathbb{E}[y(t)]$')
finalize_axes(keep_box=False)
<>:4: SyntaxWarning: invalid escape sequence '\m'
<>:4: SyntaxWarning: invalid escape sequence '\m'
/var/folders/_b/h5g1v3lj0kn0z0dftzpz4byc0000gn/T/ipykernel_60425/34763263.py:4: SyntaxWarning: invalid escape sequence '\m'
  plt.ylabel('$\mathbb{E}[y(t)]$')
array([<Axes: xlabel='$t$', ylabel='$\\mathbb{E}[y(t)]$'>], dtype=object)
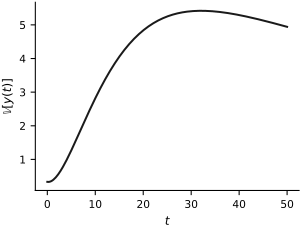
# Let's plot the variance
plt.plot(solver.t, y_v_lhs)
plt.xlabel('$t$')
plt.ylabel('$\mathbb{V}[y(t)]$')
finalize_axes(keep_box=False)
<>:4: SyntaxWarning: invalid escape sequence '\m'
<>:4: SyntaxWarning: invalid escape sequence '\m'
/var/folders/_b/h5g1v3lj0kn0z0dftzpz4byc0000gn/T/ipykernel_60425/2688720360.py:4: SyntaxWarning: invalid escape sequence '\m'
  plt.ylabel('$\mathbb{V}[y(t)]$')
array([<Axes: xlabel='$t$', ylabel='$\\mathbb{V}[y(t)]$'>], dtype=object)
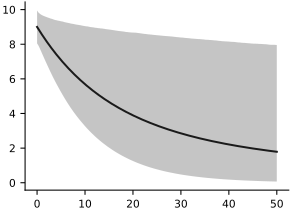
# Now, let's draw the predictive envelop
# We need the standard deviation:
y_s_lhs = np.sqrt(y_v_lhs)
y_l_lhs = np.percentile(data_lhs, 2.5, axis=0)
# An upper bound for the prediction
y_u_lhs = np.percentile(data_lhs, 97.5, axis=0)
# And let's plot it:
plt.plot(solver.t, y_m_lhs)
plt.fill_between(solver.t, y_l_lhs, y_u_lhs, alpha=0.25)
finalize_axes(keep_box=False)
array([<Axes: >], dtype=object)
Evaluating the Performance of LHS#
To test this, we need to establish a ground truth. Fortunately, we can get an analytic solution to:
It is:
We can integrate \(x_1\) and \(x_2\) analytically from this expression.
Doing so, we get the following mean solution and variance:
# Define a function to compute the expected value of the output at time t
def E_y(t):
    """
    The expected value of the output at time t.

    Arguments:
        t - The time at which we want to evaluate the expected value.

    Returns:
        The expected value of the output at time t.
    """
    if t == 0:
        return 9.
    return (90*(1-np.exp(-0.1*t))) / t
E_y =  np.vectorize(E_y)

# Define a function to compute the variance of the output at time t
def V_y(t):
    """
    The variance of the output at time t.

    Arguments:
        t - The time at which we want to evaluate the variance.

    Returns:
        The variance of the output at time t.
    """
    if t == 0:
        return (2440*0.2)/6. - E_y(t) **2

    return (2440.*(1-np.exp(-0.2*t)))/(6.*t) - E_y(t)**2
V_y = np.vectorize(V_y)
# Do some plots that compare the variance obtained by LHS to the true one
plt.plot(solver.t, V_y(solver.t), label='True variance')
plt.plot(solver.t, y_v_lhs, '-.', label='LHS (10,000)')
plt.legend(loc='best')
finalize_axes(keep_box=False)
array([<Axes: >], dtype=object)
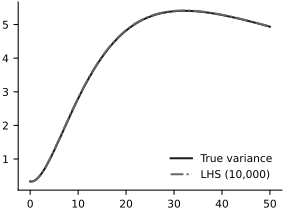
It seems close. But this is for 10,000 samples. Let’s compare Latin hypercube sampling with uniform sampling using the discrete Euclidean error in the estimated variance. Let \(V(t_i)=\mathbb{V}[y(t_i)]\) be the exact variance at output time \(t_i\), and let \(\widehat V_{\alpha,N}(t_i)\) be its estimate from \(N\) samples using method \(\alpha\), either LHS or uniform Monte Carlo. On the fixed grid of \(n_t\) output times, we compute
This is an absolute, grid-dependent error. We use the same output grid for both methods and every sample count.
# Function to compute the Euclidean error for uniform sampling
def get_MC_error(max_num_samples=100):
    """
    Compute the variance-estimate error at each Monte Carlo sample count.
    """
    y_v_true = V_y(solver.t)
    y = np.zeros(solver.num_output)
    y2 = np.zeros(solver.num_output)
    n = []
    error = []
    for i in range(max_num_samples):
        x = rng.random(2)
        y_sample = solver(x)
        y += y_sample
        y2 += y_sample ** 2
        if i % 1 == 0:    # Produce an estimate at every sample count
            n.append(i + 1)
            y_m = y / (i + 1)
            y_v = y2 / (i + 1) - y_m ** 2
            error.append(np.linalg.norm(y_v_true - y_v))
    return n, error


# Helper function to compute the Euclidean error over increasing number of samples
def _get_LHS_error(max_num_samples=100):
    """
    This function will compute the Euclidean error over increasing number of samples.

    Arguments:
        max_num_samples - The maximum number of samples to use.

    Returns:
        n - A list of sample counts.
        error - A list of Euclidean error values.
    """
    # True variance of the solver output
    y_v_true = V_y(solver.t)

    # Initialize accumulators
    y = np.zeros(solver.num_output)
    y2 = np.zeros(solver.num_output)

    # Lists to store the sample counts and Euclidean error
    n = []
    error = []

    # Create the LHS design using scipy.stats.qmc
    sampler = qmc.LatinHypercube(d=2, seed=rng)
    X = sampler.random(n=max_num_samples)  # Generate Latin Hypercube samples

    # Loop through the samples
    for i in range(max_num_samples):
        x = X[i, :]
        y_sample = solver(x)
        y += y_sample
        y2 += y_sample ** 2

        # Compute Euclidean error at every step
        if i % 1 == 0:    # Update every step (can adjust to 100 for less frequent updates)
            n.append(i + 1)
            y_m = y / (i + 1)
            y_v = y2 / (i + 1) - y_m ** 2
            error.append(np.linalg.norm(y_v_true - y_v))  # Compute the discrete Euclidean error

    return n, error

# Function to compute Euclidean error for LHS
def get_LHS_error(max_num_samples=100):
    """
    This function will compute the Euclidean error over increasing number of samples.

    Arguments:
        max_num_samples - The maximum number of samples to use.

    Returns:
        n - A list of sample counts.
        error - A list of Euclidean error values.
    """
    # Initialize lists for storing sample count and Euclidean error
    n = []
    error = []

    # Loop through to get Euclidean error over increasing number of samples
    for i in range(max_num_samples):
        if i % 1 == 0:  # Adjust here to control how often the Euclidean error is computed
            _n, _error = _get_LHS_error(i + 1)
            n.append(_n[-1])
            error.append(_error[-1])

    return n, error
# Plot the Euclidean error versus number of samples
fig, ax = plt.subplots(figsize=FIGURE_SIZES["half_standard"])
n, error = get_LHS_error(100)
n_mc, error_mc = get_MC_error(100)
mark_every = max(1, len(n) // 10)
ax.plot(
    n, error, color="black", linestyle="-", marker="o",
    markevery=mark_every, markerfacecolor="white", label="LHS",
)
ax.plot(
    n_mc, error_mc, color="0.45", linestyle="--", marker="s",
    markevery=mark_every, markerfacecolor="white", label="Uniform",
)
ax.set_xlabel("Number of samples")
ax.set_ylabel("Euclidean error")
ax.legend()
finalize_axes(keep_box=False)
array([<Axes: xlabel='Number of samples', ylabel='Euclidean error'>],
      dtype=object)
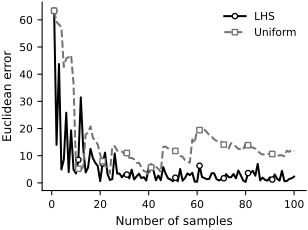
This run suggests that Latin hypercube sampling yields faster error decay than uniform sampling, but the estimator still varies across randomized designs. How can we quantify that variability? Repeat the procedure with many independent designs. The resulting empirical distribution estimates the Monte Carlo variability of the error estimator and provides error bars for it.
# Set up Monte Carlo simulation
num_exper = 100
num_samples = 25
error_lhs_samples = []
error_mc_samples = []


for i in range(num_exper):
    n_lhs, error_lhs = get_LHS_error(num_samples)
    error_lhs_samples.append(error_lhs)
    n_mc, error_mc = get_MC_error(num_samples)
    error_mc_samples.append(error_mc)

samples = np.arange(1, num_samples + 1, dtype=int)
error_lhs_samples = np.array(error_lhs_samples)
error_mc_samples = np.array(error_mc_samples)

# Compute the statistics for LHS
error_lhs_m = np.mean(error_lhs_samples, axis=0)
error_lhs_l = np.percentile(error_lhs_samples, 2.5, axis=0)
error_lhs_u = np.percentile(error_lhs_samples, 97.5, axis=0)

# Compute the statistics for uniform sampling
error_mc_m = np.mean(error_mc_samples, axis=0)
error_mc_l = np.percentile(error_mc_samples, 2.5, axis=0)
error_mc_u = np.percentile(error_mc_samples, 97.5, axis=0)
# Plot the results of the repeated sampling experiment
fig, ax = plt.subplots(figsize=FIGURE_SIZES["half_standard"])
mark_every = max(1, len(samples) // 10)
ax.fill_between(
    samples, error_lhs_l, error_lhs_u,
    facecolor="0.88", edgecolor="0.25", hatch="///",
    linewidth=0.6, alpha=0.7, label="LHS 95% interval",
)
ax.fill_between(
    samples, error_mc_l, error_mc_u,
    facecolor="white", edgecolor="0.55", hatch="\\\\",
    linewidth=0.6, alpha=0.8, label="Uniform 95% interval",
)
ax.plot(
    samples, error_lhs_m, color="black", linestyle="-", marker="o",
    markevery=mark_every, markerfacecolor="white", label="LHS mean",
)
ax.plot(
    samples, error_mc_m, color="0.35", linestyle="--", marker="s",
    markevery=mark_every, markerfacecolor="white",
    label="Uniform mean",
)
ax.set_xlabel("Number of samples")
ax.set_ylabel("Euclidean error")
ax.legend(
    loc="upper center", bbox_to_anchor=(0.5, -0.18),
    ncol=2, fontsize=7,
)
finalize_axes(keep_box=False)
array([<Axes: xlabel='Number of samples', ylabel='Euclidean error'>],
      dtype=object)
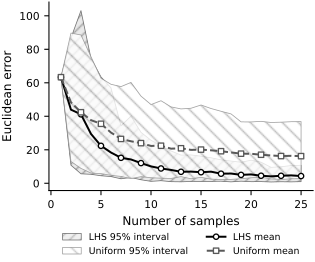
Now you can see how much more accurate Latin hypercube sampling is than uniform sampling.