

Example: Uncertainty Sampling#
We will use uncertainty sampling, which maximizes the expected information gain under the Gaussian assumptions developed in the preceding section (MacKay, 1992).
1D example#
Here is the data-generating process. (Yes, it’s just a simple python function. But pretend it’s something much more expensive to evaluate, like a physical experiment or a complex simulation.)
def data_generating_process_1d(x):
    """Stand-in for an expensive simulator or physical experiment."""
    x = x[0]  # Unpack the 1D array
    return np.sin(10*x**2) + x + 0.1*np.random.normal(size=x.shape)
Start with just one data point:
X_1d = jr.uniform(key, (1, 1))
y_1d = data_generating_process_1d(X_1d)
It is not a good idea to train the model when we have so few data. So, we will simply fix the hyperparameters of the GP to something reasonable.
def build_gp(params, X):
    """Build a 1D Gaussian process with RBF kernel."""
    k = params['amplitude']*kernels.ExpSquared(params['lengthscale'])
    return GaussianProcess(k, X, diag=params['noise_stdev']**2, mean=params['mean'])

params = {
    'mean': 0.0,
    'amplitude': 4.0,
    'lengthscale': 0.15,
    'noise_stdev': 0.1
}

def eval_gp(Xq, X, y, params):
    gp = build_gp(params, X)
    _, cond_gp = gp.condition(y, Xq)
    return cond_gp

Xq_plt = jnp.linspace(0, 1, 1000)[:, None]
cond_gp = eval_gp(Xq_plt, X_1d, y_1d, params)
And let’s visualize the uncertainty in the model’s prediction:
def plot_posterior_uncertainty_1d(X, y, params, ax=None, legend=True):
    X_pred = jnp.linspace(0, 1, 100)[:, None]
    cond_gp = eval_gp(X_pred, X, y, params)
    mean = cond_gp.mean
    std = jnp.sqrt(cond_gp.variance)
    samples = cond_gp.sample(key, shape=(5,))
    if ax is None:
        fig, ax = plt.subplots(figsize=FIGURE_SIZES["half_standard"])
    ax.plot(X_pred, mean, label="Predictive mean" if legend else None)
    ax.fill_between(X_pred.squeeze(), mean - 2*std, mean + 2*std, alpha=0.2, label=r"$\pm 2\sigma$" if legend else None)
    ax.scatter(X, y, label="Observations" if legend else None)
    ax.plot(X_pred, samples.T, color='tab:red', lw=0.5, alpha=0.5)
    if legend:
        # ax.legend(loc='upper right')
        ax.legend(loc='best')
    ax.set_ylim(-2.0, 4.0)
    ax.set_xlabel(r"$x$")
    ax.set_ylabel(r"$y$")
    finalize_axes(keep_box=False)
    return ax

plot_posterior_uncertainty_1d(X_1d, y_1d, params);
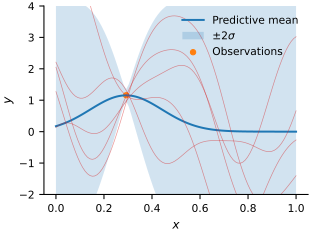
Uncertainty is lower near the data point and high everywhere else. Let’s find the “best” next point to evaluate. Since our goal is to create the “best” model, we’ll select the point where there is maximum predictive uncertainty.
next_x = get_next_x(X_1d, y_1d, params)
ax = plot_posterior_uncertainty_1d(X_1d, y_1d, params, legend=False)
ax.axvline(next_x, color="red", linestyle="--", label=r"Next $x$")
ax.legend(loc='upper right');
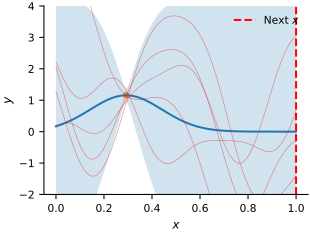
The “best” point is near the boundary. Let’s generate a data value at this point and plot a new fitted GP:
key, key_data, key_train = jr.split(key, 3)
next_y = data_generating_process_1d(next_x)
X_1d = jnp.concatenate([X_1d, next_x[None, :]], axis=0)
y_1d = jnp.concatenate([y_1d, next_y[None]], axis=0)

ax = plot_posterior_uncertainty_1d(X_1d, y_1d, params, legend=False)
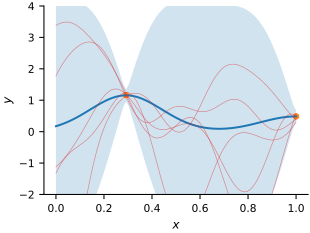
Let’s repeat this process a few more times:
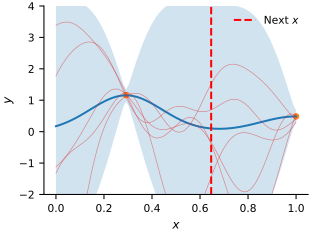
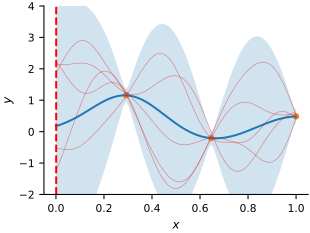
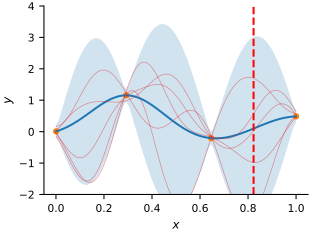
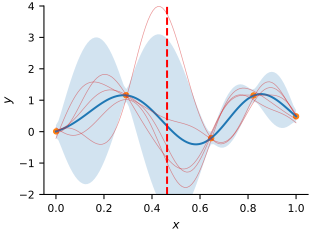
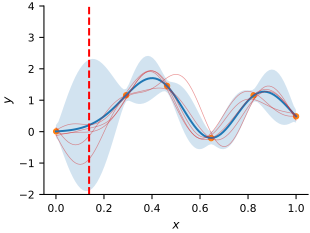
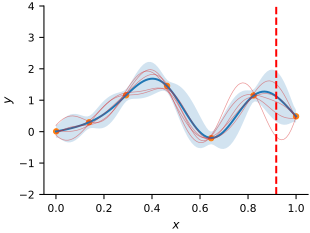
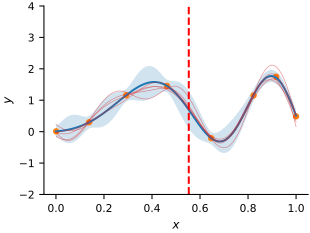
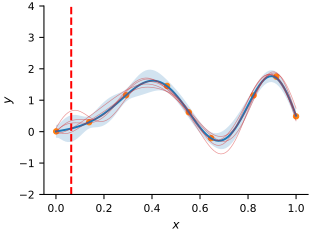
In a realistic scenario, we would keep going until the epistemic uncertainty is low enough or we run out of computational budget.
2D example#
Let’s do the same thing in 2D. The data-generating process is:
@jit
def data_generating_process_2d(x):
    """Stand-in for an expensive simulator or physical experiment."""
    x1, x2 = x[0], x[1]
    f1 = 1/2*jnp.sin(5/2*x1 + 2/3*x2)**2 + 2/3*jnp.exp(-x1*(x2 - 0.5)**2)*jnp.cos(4*x1 + x2)**2
    f2 = x1*(1 - x1)*x2*(1 - x2)*10
    alpha = jax.nn.sigmoid(10*(x2 - x1))
    return alpha*f1 + (1 - alpha)*f2
Again, pretend data_generating_process_2d is actually some expensive process.
Let’s start with a few data points:
X_2d = qmc.LatinHypercube(d=2).random(n=5)
y_2d = vmap(data_generating_process_2d)(X_2d)
Build a GP:
def build_gp(params, X):
    """Build a 2D Gaussian process with RBF kernel."""
    amp = params['amplitude']
    ell = params['lengthscales']
    sigma = params['noise_stdev']
    k = amp*transforms.Linear(1/ell, kernels.ExpSquared())  # Must be constructed this way if ell is a vector
    return GaussianProcess(k, X, diag=sigma**2, mean=params['mean'])

# Fixed hyperparameters
params = {
    'mean': 0.0,
    'amplitude': 4.0,
    'lengthscales': jnp.array([0.3, 0.3]),  # Set these to different values for an anisotropic GP
    'noise_stdev': 0.01
}

def eval_gp(Xq, X, y, params):
    gp = build_gp(params, X)
    _, cond_gp = gp.condition(y, Xq)
    return cond_gp

X1, X2 = jnp.meshgrid(jnp.linspace(0, 1, 30), jnp.linspace(0, 1, 30))
Xq_plt = jnp.stack([X1.ravel(), X2.ravel()], axis=1)
cond_gp = eval_gp(Xq_plt, X_2d, y_2d, params)
Find the best next point at which to collect data:
next_x = get_next_x(X_2d, y_2d, params)
And plot:
ax, unc_clim = plot_posterior_uncertainty_2d(X_2d, y_2d, params)
ax[1].plot(next_x[0], next_x[1], "rx", ms=6, mew=2, label="Next $x$")
ax[2].plot(next_x[0], next_x[1], "rx", ms=6, mew=2, label="Next $x$")
ax[1].legend(loc='upper right');
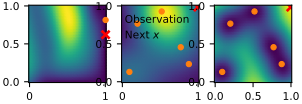
The highest uncertainty is at the edge of the domain, so that is where the next best point is.
Let’s do a few more iterations of active learning:
plot_iter = [0, 1, 2, 3, 4, 5, 10, 20]
for i in range(plot_iter[-1] + 1):
    next_x = get_next_x(X_2d, y_2d, params)

    if i in plot_iter:
        ax, _ = plot_posterior_uncertainty_2d(X_2d, y_2d, params, unc_clim=unc_clim)
        ax[1].plot(next_x[0], next_x[1], "rx", ms=6, mew=2, label="Next $x$")
        ax[2].plot(next_x[0], next_x[1], "rx", ms=6, mew=2, label="Next $x$")
        if i == 0:
            ax[1].legend(loc='upper right')

    key, key_data, key_train = jr.split(key, 3)
    next_y = data_generating_process_2d(next_x)
    X_2d = jnp.concatenate([X_2d, next_x[None, :]], axis=0)
    y_2d = jnp.concatenate([y_2d, next_y[None]], axis=0)
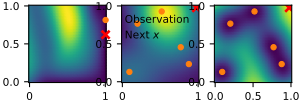
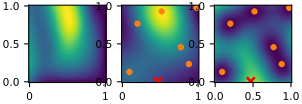
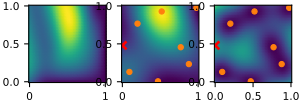
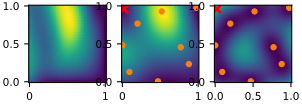
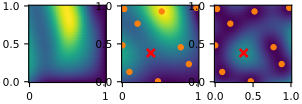
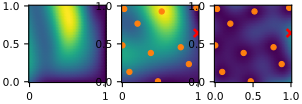
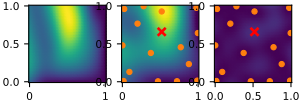
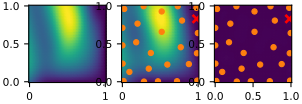
We have created a model in an optimally efficient manner (in terms of reducing epistemic uncertainty).