

Example: Surrogate for the Stochastic Heat Equation with Principal Component Analysis#
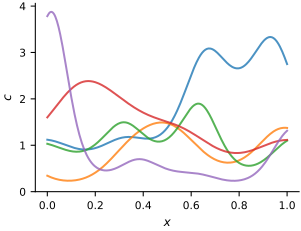
In the previous example, we built a surrogate for the solution to the stochastic (steady-state) heat equation at a single point in space. In this example, we will build a surrogate for the entire temperature field.
We will reuse the same probability measure on conductivity \(c\), i.e.,
where \(g\) is a Gaussian process. As before, we implement it with the Karhunen–Loève expansion.
k = 0.5*kernels.ExpSquared(scale=0.1)
kle = build_kle(k, nq=1000, alpha=0.95, input_dim=1)

def c(x, xi):
    """Compute the random thermal conductivity field for a given xi."""
    return jnp.exp(kle(x, xi))
array([<Axes: xlabel='$x$', ylabel='$c$'>], dtype=object)
Reduce dimensionality of the output with PCA#
The goal is to propagate uncertainty from one stochastic function (the conductivity field) to another stochastic function (the temperature field). This requires approximating the infinite-dimensional fields with something finite-dimensional.
We have already represented the input field with a finite number of Karhunen–Loève expansion coefficients (as done in the previous example). In a similar vein, we will represent the output temperature field with a finite number of PCA coefficients.
Let’s do it. The companion notebook reuses the heat-equation solver of the previous example.
solver = SteadyStateHeat1DSolver(c=c, nx=500)
Next, create some training (and testing) data:
xis = []
us = []
for i in range(100):
    key, key_xi = jr.split(key)
    xi = jr.normal(key_xi, shape=(kle.num_xi,))
    x, y = solver(xi)
    xis.append(xi)
    us.append(y)
xis = jnp.stack(xis, axis=0)
us = jnp.stack(us, axis=0)

from sklearn.model_selection import train_test_split
key, key_split = jr.split(key)
xi_train, xi_test, u_train, u_test = train_test_split(xis, us, test_size=0.1, random_state=int(jr.randint(key_split, shape=(), minval=0, maxval=1e6)))
Finally, we do PCA on the training temperature fields; the implementation is in the companion notebook.
class PrincipalComponentAnalysis(object):
    """A convenience class for performing principal component analysis (PCA)."""

    mean: Float[Array, "n_features"]
    U: Float[Array, "n_features n_components"]
    s: Float[Array, "n_components"]
    coefficients: Float[Array, "n_features n_components"]
    Vt: Float[Array, "n_components n_features"]

    def __init__(self, X, alpha=0.9):
        # Compute data mean
        x_bar = jnp.mean(X, axis=0)
        B = X - x_bar

        # Compute SVD
        U, s, Vt = jnp.linalg.svd(B, full_matrices=False)

        # Select the however many components explain alpha% of the energy
        energy = jnp.cumsum(s**2)/jnp.sum(s**2)
        n_components = jnp.arange(energy.shape[0])[energy > alpha][0] + 1
        U = U[:, :n_components]
        s = s[:n_components]
        Vt = Vt[:n_components]

        self.mean = x_bar
        self.U = U
        self.s = s
        self.coefficients = jnp.einsum('ij,j->ij', U, s)
        self.Vt = Vt

    @property
    def n_components(self):
        return self.Vt.shape[0]

    @property
    def principal_components(self):
        return self.Vt

    def project(self, X, n_components=None):
        """Project the data onto the principal components.

        Parameters
        ----------
        X : Float[Array, "n_samples n_features"]
            The data to project.
        n_components : int
            The number of principal components to use.
            If `None`, all components are used.

        Returns
        -------
        Float[Array, "n_samples n_components"]
        """
        if n_components is None:
            n_components = self.n_components
        return self.mean + jnp.einsum('ij,jk->ik', X, self.Vt[:n_components])
pca = PrincipalComponentAnalysis(u_train, alpha=0.95)
Both the input and output of our stochastic model can now be expressed as a weighted sum of fixed functions. Let’s visualize what these fixed functions are:
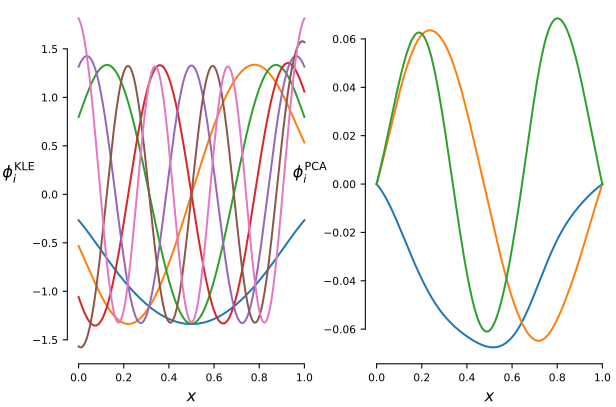
To reiterate, every log-conductivity field can be approximately represented as the weighted sum
where the fixed functions \(\{\phi^\text{KLE}_i | i=1, \dots, N_\text{KLE}\}\) are shown on the left in the figure above.
Likewise, every temperature field can be approximately represented as the weighted sum
where \(\bar{u}\) is the mean of the training temperature fields and the fixed functions \(\{\phi^\text{PCA}_i | i=1, \dots, N_\text{PCA}\}\) are shown on the right in the figure above.
Surrogate for the stochastic model#
We will now train a surrogate to approximate the mapping \(\xi \mapsto \eta\) (i.e., the mapping from the input’s KLE coefficients to the output’s PCA coefficients). This will enable fast uncertainty propagation over fields!
However, instead of directly creating one big multi-input-multi-output surrogate, we will train a separate Gaussian process surrogate for each PCA coefficient. So, there will be a GP for the mapping \(\xi \mapsto \eta_1\), another GP for \(\xi \mapsto \eta_2\), and another for \(\xi \mapsto \eta_3\), and so on.
Here we go:
init_params = {
    'log_amplitude': 1.0,
    'log_lengthscale': -jnp.ones(xis.shape[1]),  # Different lengthscale for each input dimension
}

pca_datasets = []
optimized_params = []
key, subkey = jr.split(key)
for i in range(pca.n_components):
    key, key_train = jr.split(key)
    X = xi_train
    y=pca.coefficients[:, i]
    p, _ = train_gp(
        init_params,
        X=X,
        y=y,
        num_iters=1000,
        learning_rate=1e-2,
        batch_size=100,
        key=subkey
    )
    optimized_params.append(p)
    pca_datasets.append((X, y))
Great! We now have a trained GP for each PCA coefficient of the temperature field. Let’s group it all together in a single class for convenience:
surrogate = Surrogate(optimized_params, pca_datasets, x, pca)
And let’s test our surrogate’s accuracy. First, let’s predict the full temperature field for each test case:
u_test_pred = surrogate(xi_test)
And let’s compare them to the true fields with a parity plot:
array([<Axes: xlabel='True', ylabel='Predicted'>], dtype=object)
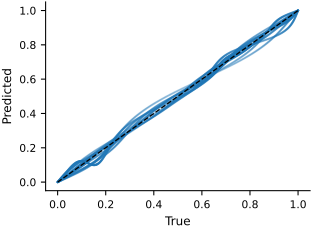
The held-out temperature predictions lie close to the reference values.
Uncertainty propagation#
We can now propagate uncertainty by evaluating the surrogate at many input samples.
For example, let’s compute some quantiles for the distribution of \(u(x)\):
n_samples = 1000
key, key_xi = jr.split(key)
xi = jr.normal(key_xi, shape=(n_samples, kle.num_xi))
u = surrogate(xi)

u_mean = jnp.mean(u, axis=0)
u_025, u_975 = jnp.quantile(u, jnp.array([0.025, 0.975]), axis=0)
array([<Axes: xlabel='$x$', ylabel='$u$'>], dtype=object)
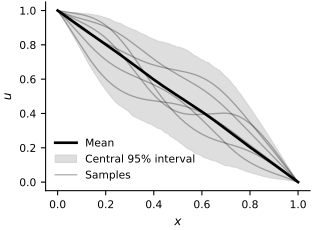
With this surrogate, we have propagated uncertainty through a partial differential equation, from an uncertain conductivity field to an uncertain temperature field. The finite KLE and PCA representations make repeated evaluation much cheaper than solving the PDE for every input sample.
Surrogates for stochastic models (like this one) can enable downstream tasks that were prohibitively expensive before. For example, if we include some design variables in the input, we could perform design optimization under uncertainty.
Exercises#
Play with the amount of training data, as well as the number of KLE and PCA coefficients (controlled by the alpha parameters in the companion notebook).