
The Karhunen–Loève Expansion#
For numerical methods that discretize random fields through the Karhunen–Loève expansion, see Betz et al. (2014).
Consider a Gaussian process on a bounded domain \(D\subset\mathbb{R}^d\), with square-integrable mean \(m\) and covariance \(k\) continuous on its closure. These assumptions give finite integrated variance, \(\int_D k(\mathbf{x},\mathbf{x})\,d\mathbf{x}<\infty\): the field has a finite total amount of uncertainty to distribute among its modes. Write:
where \(m\) is the mean function and \(k\) is the covariance function. The Karhunen–Loève expansion (KLE) of \(f\) allows us to write it as:
where the random variables
are independent, and \(\lambda_i\) and \(\phi_i(\mathbf{x})\) are the eigenvalues and eigenfunctions, respectively, of the covariance operator, ordered so that \(\lambda_1\geq\lambda_2\geq\cdots\geq0\). The expansion converges in mean square when averaged over \(D\). The modes satisfy
Because a covariance operator is positive semidefinite, its eigenvalues are nonnegative, and its eigenfunctions can be chosen orthonormal:
Truncated KLE#
Usually, we truncate the KLE to a finite order \(M\), i.e., we write
But how do we pick \(M\) in practice?
In order to answer this question, notice that the variance of the field at the point \(\mathbf{x}\) is given by:
The energy of the field \(\mathcal{E}[f]\) is defined to be
where we have used the orthonormality of the \(\phi_i\)’s. The energy of the field is a measure of the total variance of the field. The idea is to select \(M\) so that the energy of the truncated field \(f_M\) captures a fraction \(\alpha\) of the energy of the original field. That is, we pick the smallest \(M\) so that
or
Typically, \(\alpha = 0.95\).
Dimensionality reduction#
The KLE allows us to reduce the dimensionality of random fields. This is extremely useful in uncertainty propagation and model calibration tasks. For example, in uncertainty propagation, by employing the KLE one has to deal with a finite set of Gaussian random variables \(\xi_i\) instead of an infinite-dimensional Gaussian random field.
Numerically, we use the Nyström approximation: choose quadrature points and weights, replace the covariance integral by a weighted sum, and solve the resulting matrix eigenproblem.
The companion notebook implements this construction in JAX using tinygp as the function build_kle, which the heat-equation examples below reuse.
class KarhunenLoeveExpansion(eqx.Module):
    """
    The Karhunen Loeve Expansion of a Gaussian random field.
    It uses the Nystrom approximation to do it.

    Parameters
    ----------
    gp : tinygp.GaussianProcess
        The Gaussian process to expand.
    wq : Float[Array, "n_q"]
        The quadrature weights.
    alpha : float
        The percentage of the energy of the field that you want to keep.
    """
    gp: GaussianProcess
    lambd: Float[Array, "n_xi"]
    v: Float[Array, "n_xi n_q"]
    wq: Float[Array, "n_q"]

    def __init__(self, gp, wq, alpha=0.9):
        # Get the covariance (evaluated at the quadrature points).
        # If our gp is conditioned on some observations, then this will be the posterior covariance.
        Kq = gp.covariance

        # Get the eigenvalues/eigenvectors of the discretized covariance function
        B = jnp.einsum('ij,j->ij', Kq, wq)
        lam, v = jax.scipy.linalg.eigh(B, overwrite_a=True)
        lam = lam[::-1]
        lam = lam.at[lam <= 0.].set(0.)

        # Keep only the eigenvalues that explain alpha% of the energy
        energy = jnp.cumsum(lam) / jnp.sum(lam)
        i_end = jnp.arange(energy.shape[0])[energy > alpha][0] + 1
        lam = lam[:i_end]
        v = v[:, ::-1]
        v = v[:, :i_end]

        self.gp = gp
        self.lambd = lam
        self.v = v
        self.wq = wq

    @property
    def energy(self):
        """The energy captured by the truncated expansion."""
        return jnp.sum(self.lambd)

    @property
    def num_xi(self):
        """The number of terms kept in the truncated expansion."""
        return self.lambd.shape[0]

    def eval_phi(self, x):
        """Evaluate the eigenfunctions at x."""
        Kc = self.gp.kernel(x, self.gp.X)  # Evaluate the cross-covariance between the query points (x) and the quadrature points (self.gp.X)
        phi = jnp.einsum("i,ji,j,rj->ri", 1/self.lambd, self.v, self.wq**0.5, Kc)
        return phi

    def __call__(self, x, xi):
        """Evaluate the expansion at x and xi."""
        phi = self.eval_phi(x)
        return vmap(self.gp.mean_function)(x) + jnp.dot(phi, xi*self.lambd**0.5)
And here is a convenience function that builds the KLE:
def build_kle(
    k,
    nq=100,
    alpha=0.9,
    Xq=None,
    wq=None,
    Xobs=None,
    yobs=None,
    *,
    input_dim
):
    """Build the Karhunen-Loève expansion of a Gaussian process.

    Parameters
    ----------
    k : tinygp.kernels.Kernel
        The kernel of the Gaussian process.
    nq : int
        The number of quadrature points.
    alpha : float
        The percentage of the energy of the field that you want the expansion to capture.
        This determines the number of terms in the expansion.
    Xq : jnp.ndarray
        The quadrature points.
    wq : jnp.ndarray
        The quadrature weights
    Xobs : jnp.ndarray
        The observed points.
    yobs : jnp.ndarray
        The observed values.
    input_dim : int
        The dimension of the input space.

    Returns
    -------
    kle : KarhunenLoeveExpansion
        The Karhunen-Loève expansion of the Gaussian process.
    """
    # Generate quadrature points
    if Xq is None:
        if input_dim == 1:
            Xq = jnp.linspace(0, 1, nq)[:, None]
            wq = jnp.ones((nq,))/nq
        elif input_dim == 2:
            nq = int(jnp.sqrt(nq))
            x = jnp.linspace(0, 1, nq)
            X1, X2 = jnp.meshgrid(x, x)
            Xq = jnp.hstack([X1.flatten()[:, None], X2.flatten()[:, None]])
            wq = jnp.ones((nq**2,))/nq**2
        else:
            raise NotImplementedError('For more than 2D, please supply quadrature points and weights.')

    # Build the Gaussian process
    if Xobs is not None:
        _, gp = GaussianProcess(k, Xobs, diag=1e-6).condition(y=yobs, X_test=Xq)
    else:
        gp = GaussianProcess(k, Xq, diag=1e-6)

    # Build the KLE
    return KarhunenLoeveExpansion(gp, wq, alpha)
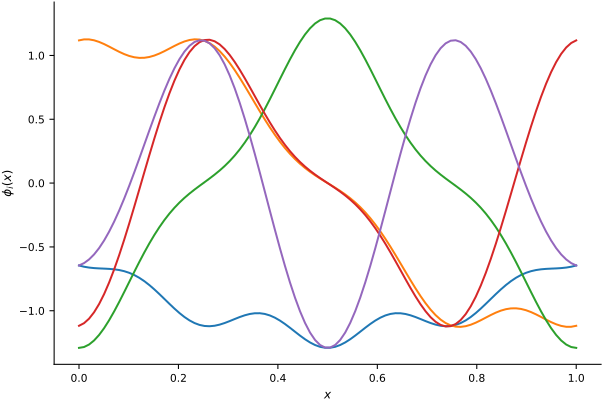
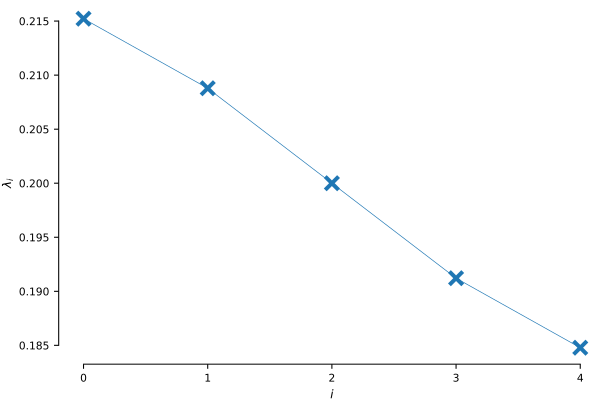
Let’s just plot the eigenfunctions/values of the square exponential (SE) covariance function:
k = kernels.ExpSquared(scale=0.1)
kle = build_kle(k, nq=5, alpha=.9, input_dim=1)
Exercises#
The estimated eigenfunctions and eigenvalues do not look very accurate. Perhaps, you need to increase the number of quadrature points used in the Nystrom approximation. Try
nq=20. How do they look now?How are the eigenvalues of the covariance function affected if you decrease the length scale?
The default variance of the square exponential is one. Try changing it to 2. What changed, if anything?
Experiment with different covariance functions, e.g., the
PoweredExponentialor theMatern32.
Varying the length scale#
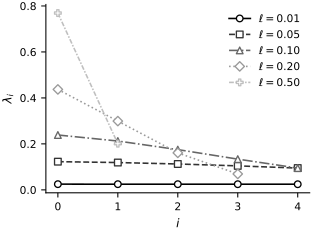
Let’s vary the length scale of the SE and see what happens to the eigenvalues.
lengthscales = [0.01, 0.05, 0.1, 0.2, 0.5]
kles = [build_kle(kernels.ExpSquared(scale=ell), nq=100, alpha=.9, input_dim=1) for ell in lengthscales]
array([<Axes: xlabel='$i$', ylabel='$\\lambda_i$'>], dtype=object)
Exercises#
The larger the length scale (and therefore the smoother the GP samples), the faster the eigenvalues decay to zero. Why? Hint: Think about the RBF eigenfunctions we plotted earlier—the first was the smoothest, and each subsequent eigenfunction got more “wiggly”.
Sampling from the random field using \(\xi\)#
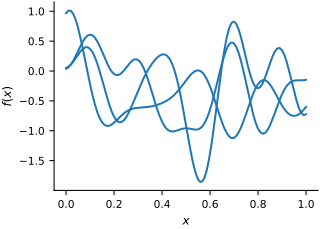
Let’s plot some samples \(f \sim \operatorname{GP}(0, k)\) where \(k\) is the exponential kernel.
k = kernels.Exp(scale=0.1)  # Exponential kernel. GP samples should look jagged.
kle = build_kle(k, nq=100, alpha=0.8, input_dim=1)
array([<Axes: xlabel='$x$', ylabel='$f(x)$'>], dtype=object)
Exercises#
The figure shows the samples that we get from the KLE using an exponential covariance function. They look too smooth. The samples are supposed to be nowhere differentiable. What is the problem?
How many terms did you need to get samples that really look like samples from an exponential GP?
KLE for GP with Observed Data#
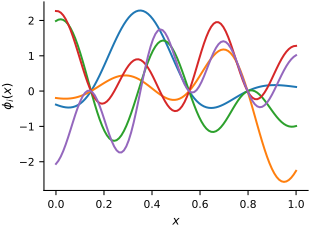
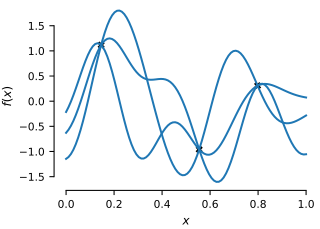
Here we take a look at the KLE of a GP where we have made some input/output observations
# Generate some input/output pairs randomly.
key, key_X, key_y = jrandom.split(key, 3)
X = jrandom.uniform(key_X, shape=(3, 1))
y = jrandom.normal(key_y, shape=(3,))

k = kernels.ExpSquared(scale=0.1)
kle = build_kle(k, nq=100, alpha=0.9, Xobs=X, yobs=y, input_dim=1)
Exercises#
What is the value of the basis functions at the points where we have observations?
Experiment with various covariance functions and hyper-parameters.
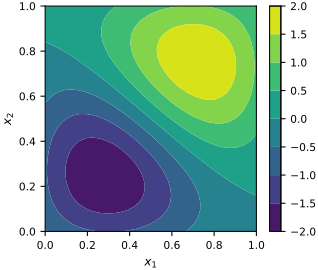
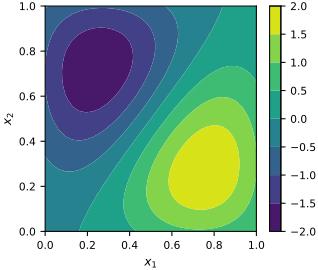
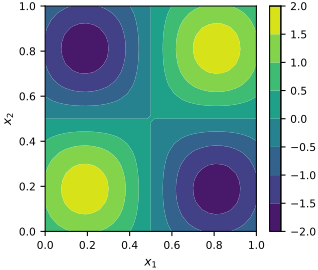
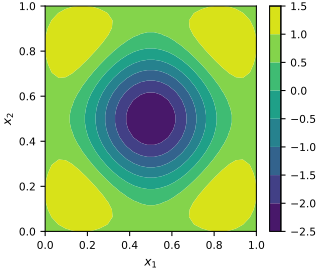
Playing in two-dimensions#
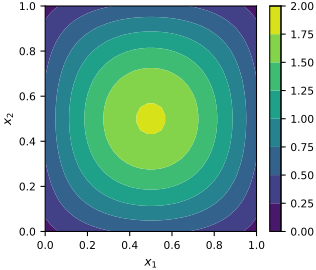
Let’s experiment with these ideas in two dimensions.
WITH_OBSERVATIONS = False  # Set to true to see the eigenfunctions when there are observations.

k = kernels.ExpSquared(scale=0.1)

if WITH_OBSERVATIONS:
    key, key_X, key_y = jrandom.split(key, 3)
    X = jrandom.uniform(key_X, shape=(10, 2))
    y = jrandom.normal(key_y, shape=(10,))
    kle = build_kle(k, nq=100, alpha=0.9, input_dim=2, Xobs=X, yobs=y)
else:
    kle = build_kle(k, nq=100, alpha=0.9, input_dim=2)
Number of terms: 49
Exercises#
Try plotting some eigenfunctions with higher index.
Try adding some observations.
Now that you are becoming familiar with the code, try to plot a few samples from this random field.